
92 posts tagged with "EventCatalog"

Explore EventCatalog articles and updates about EventCatalog.

View All Tags

Whats new in EventCatalog - August 2026
· 11 min read
David Boyne
Founder of EventCatalog

Welcome to the monthly update for EventCatalog. In July we released EventCatalog v4 and introduced systems as a new way to document software architecture. In August we focused on what happens when that architecture grows across teams, repositories, and thousands of resources.

The headline is EventCatalog Federation v2, a new built-in workflow for composing team-owned catalogs into one verified organization catalog. We also shipped a catalog-wide Architecture Graph, custom sidebars for every resource, a major upgrade to the EventCatalog Linter, and plenty of improvements underneath.

We started the month on 4.3.4 and finished on 4.10.3.

EventCatalog Federation v2

EventCatalog works well as a central catalog, but large organizations often want teams to own their architecture documentation next to their code while still giving everyone one place to explore the wider system.

In August we released EventCatalog Federation v2.

Federation is now built into EventCatalog. An organization catalog lists the team catalogs it wants to compose, then one command fetches those sources, validates ownership and relationships across them, and materializes a connected view for people and AI agents.

eventcatalog.config.js
export default {
federation: {
sources: [
{ id: 'acme/payments', source: 'github:acme/payments-catalog' },
{ id: 'acme/orders', source: 'github:acme/orders-catalog' },
{ id: 'acme/fulfillment', source: 'file:../fulfillment-catalog' },
],
},
};

Then run:

npx eventcatalog federate

The important change from the first version is the contract. Federation v1 cloned repositories and copied configured directories. Federation v2 indexes catalogs and resolves their architecture graph. Teams reference resources owned by other teams instead of copying them, and collisions fail closed instead of being hidden by last-write-wins behavior.

Read the EventCatalog Federation docs

Each run also writes an eventcatalog.lock file with the resolved source state, uses a content-addressed cache, and restores the previous output if a run fails. Diagnostics for duplicate ownership, missing resources, unresolved versions, type conflicts, and asset collisions can be configured as off, warn, or error.

Federation can pull from GitHub or local folders, which means you can test the whole workflow on your machine before wiring it into CI. Team-owned custom components and public assets can come across too, while central catalog components still take precedence.

This is the first working version of the new model and we are looking for feedback. You can read more in the Federation v2 announcement or follow the Federation guide to try it.

See your whole architecture as a graph

Systems and context maps give you deliberate, curated views of an architecture. Sometimes you need the opposite: one map that starts with everything and lets you explore from there.

EventCatalog 4.5.0 introduced the new Architecture Graph, a catalog-wide force-directed graph of your domains, systems, services, agents, messages, flows, entities, containers, data products, teams, and the relationships between them.

You can search for any resource, click it to focus on its neighbourhood, change how many hops you want to see, and switch lenses to group the graph around domains, systems, owners, or resource types. Double-clicking a node opens its documentation.

The graph renders to a single canvas and keeps its wire format compact, so it is designed to stay responsive even when a catalog contains thousands of resources. It is opt-in while in beta:

eventcatalog.config.js
export default {
visualiser: {
architectureGraph: {
enabled: true,
},
},
};

At the end of the month we also added the <ArchitectureGraph/> component, so you can embed a focused view directly into a domain, system, service, message, or custom documentation page.

<ArchitectureGraph depth="3" lens="messages" />

The embedded graph starts from the resource being documented. Readers can explore locally, then open the same state full screen when they need more room. The component works even if the full-page graph is not enabled.

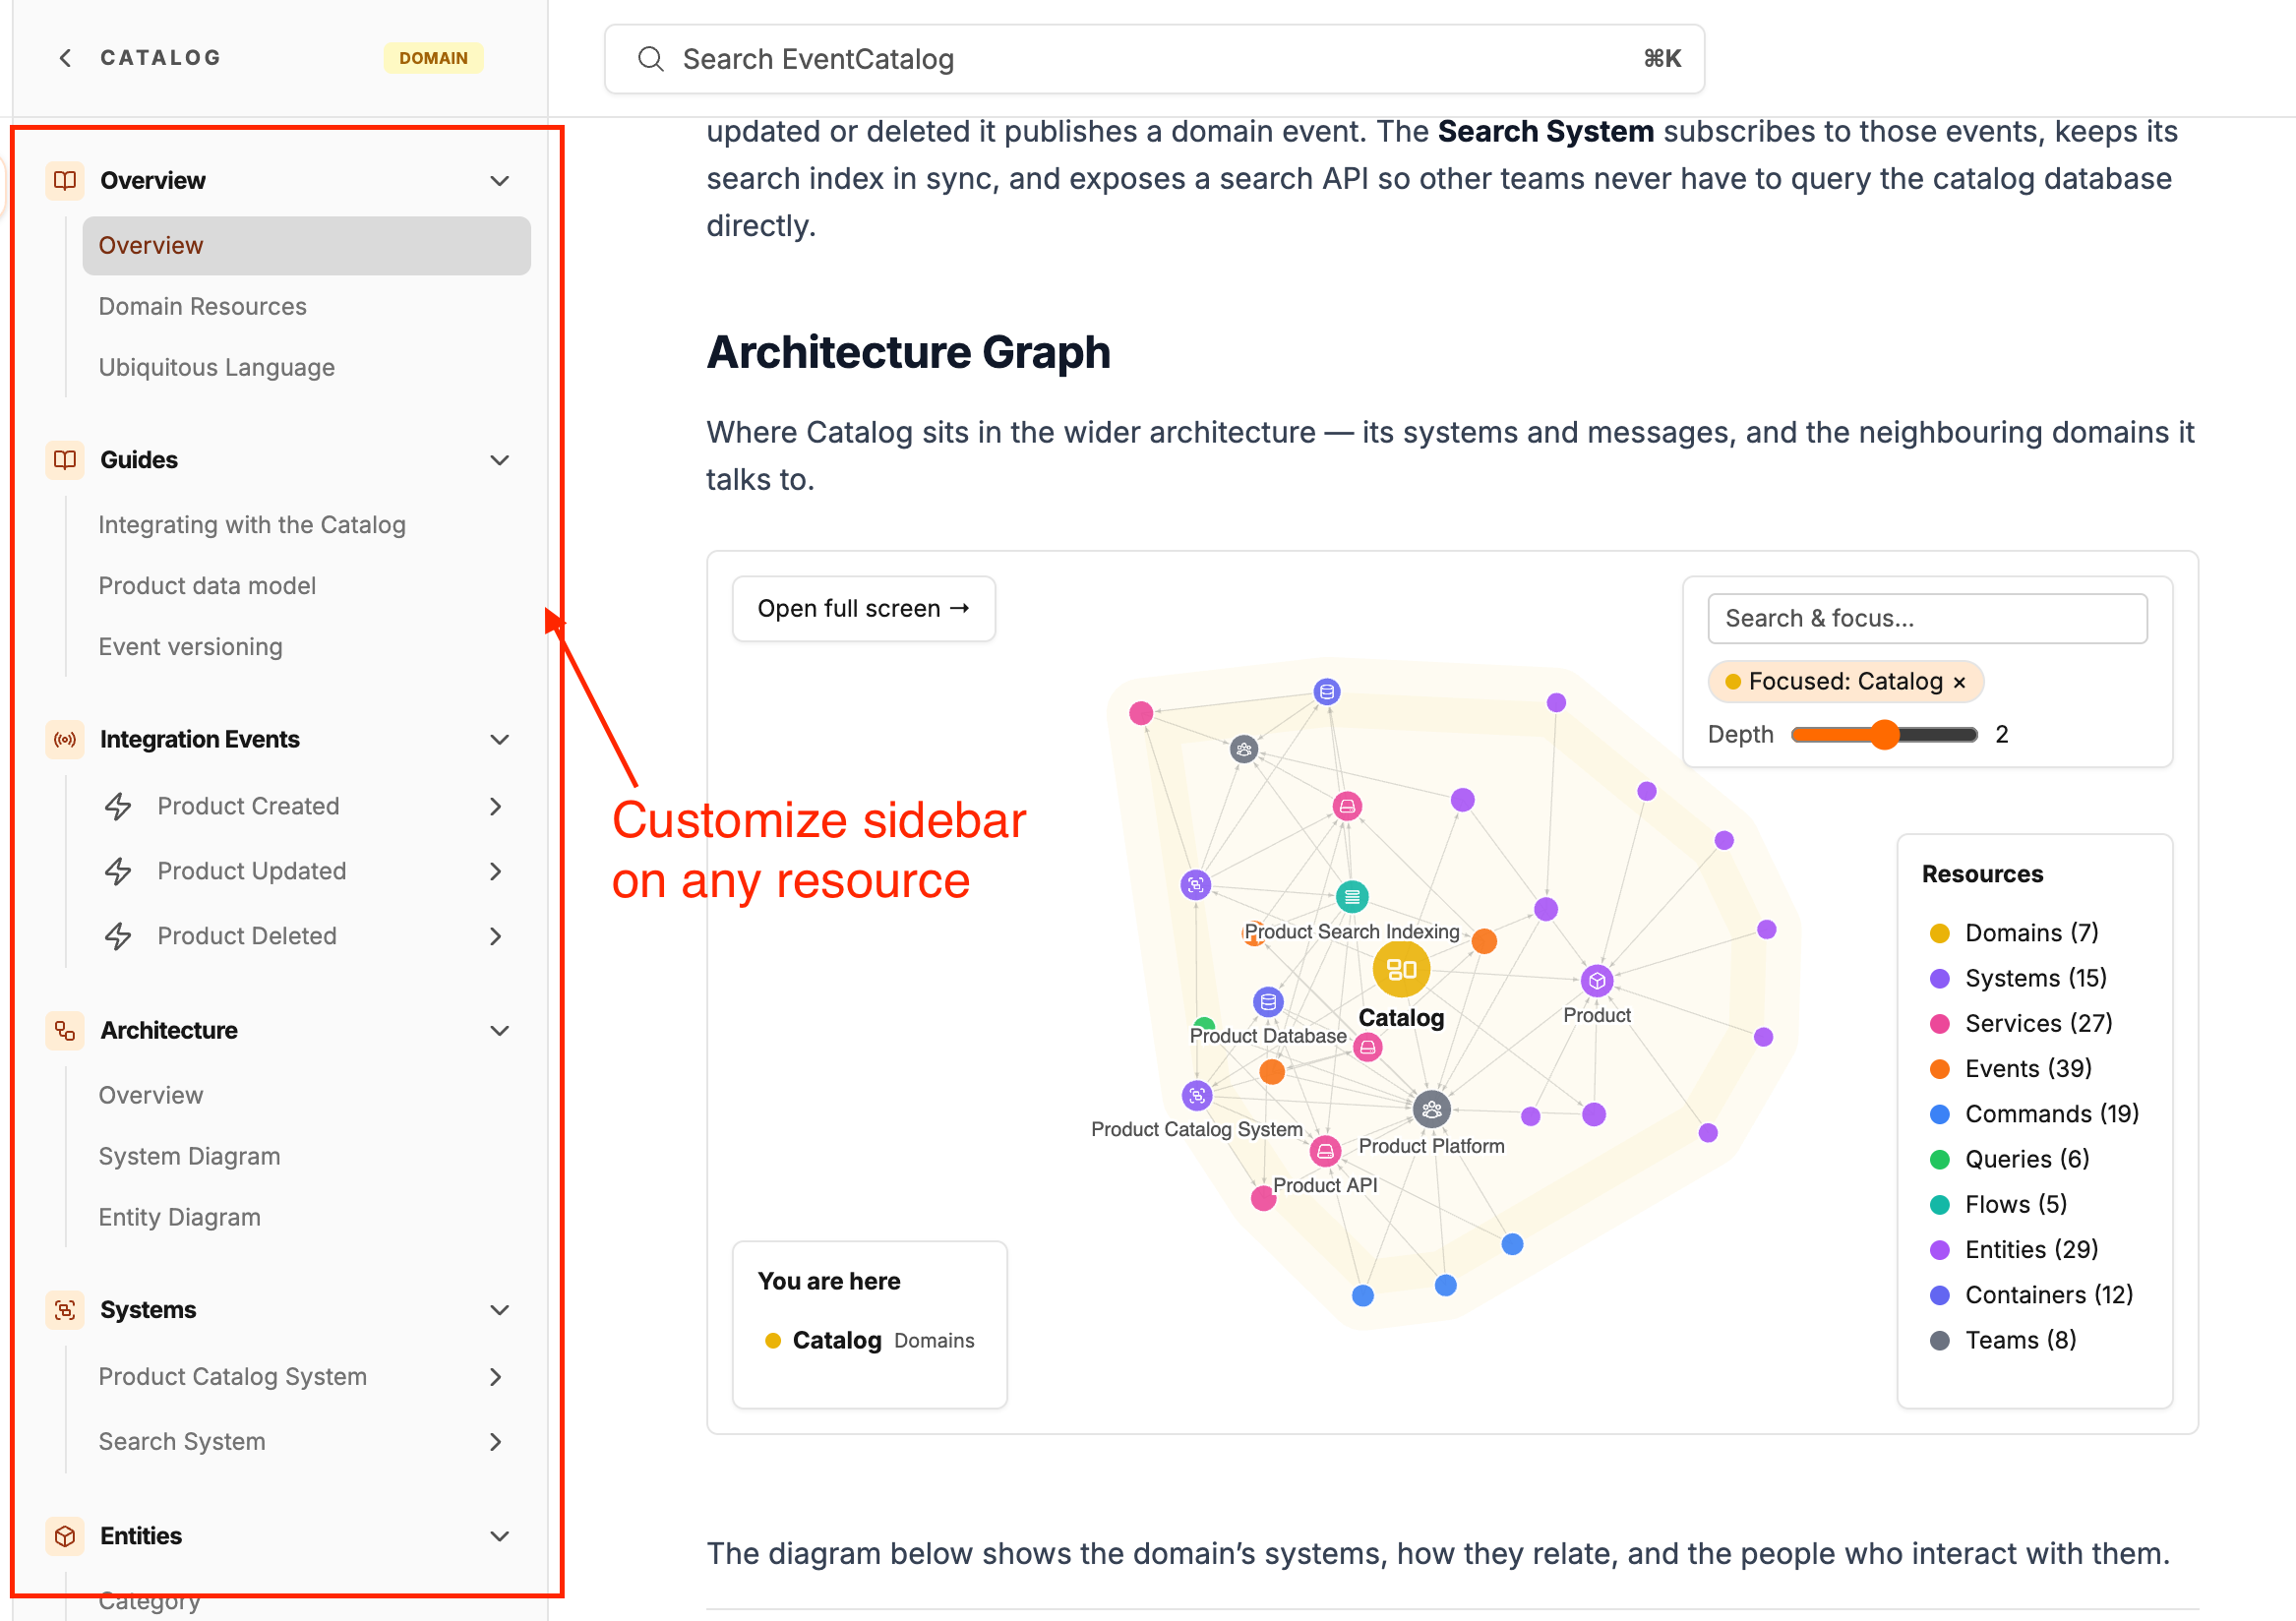
Build a sidebar around your readers

Generated resource sidebars are useful because they stay up to date automatically. But the most useful order for EventCatalog is not always the most useful order for your readers.

EventCatalog 4.10.0 adds custom resource sidebars. Add a sidebar.json next to any resource's index.mdx and you can define the navigation for that resource yourself.
domains/Payments/sidebar.json
{
"sections": [
{ "section": "$quick-reference", "title": "Start here" },
{
"title": "Guides",
"pages": ["[[doc|guides/onboarding]]"]
},
{ "section": "$services", "title": "APIs and workers" },
{ "section": "$domain-events", "title": "Integration contracts" },
{ "section": "$decision-records", "collapsed": true }
]
}

The $sections remain live as your catalog changes, while custom groups can mix documentation, specifications, schemas, resource references, and normal links. Groups can be nested or collapsed, and versioned resources inherit the sidebar from the resource folder unless they define their own.

If a token, document, specification, or schema cannot be resolved, the build fails with the file and valid options. That makes a custom sidebar safe to maintain rather than another navigation file that silently drifts.

A much stronger EventCatalog Linter

The EventCatalog Linter received one of its largest upgrades so far in August.

New rules now catch unknown frontmatter fields, unrecognised Markdown files, and file references that point at missing schemas, specifications, data product contracts, or public icons. Misspelled fields include suggestions, and x- custom properties continue to work as expected.

Findings now include the exact line and column, version ranges behave the same way as EventCatalog core, and missing resources are reported separately from references to versions that do not exist.

npx @eventcatalog/linter --init

The new --init command creates a fully commented .eventcatalogrc.js with every rule and its default severity. We also added --quiet, --max-warnings, and --no-color, fixed the checked-file summary, and made CI output quieter and easier to scan.

Channel maps

Channels now have their own architecture maps.

A big thank you to Jonas Lagoni, who contributed this feature in #2756.

A channel map shows the producers and messages that publish into the channel, the services and agents that consume from it, and the channels it routes to or receives routes from. Routed chains remain connected all the way through, so you can follow how a message enters one channel and reaches a consumer through another.

You can add <NodeGraph /> to a channel page, or open the Architecture → Map link in its sidebar when the visualiser is enabled.

EventCatalog Scale now supports monthly subscriptions

EventCatalog Scale is now available month-to-month alongside annual billing, giving teams more flexibility to get started and cancel at any time.

Other project improvements

  • Customizable sidebars for any resource using sidebar.json (#2832)
  • New <ArchitectureGraph/> component for resource and custom documentation pages (#2834)
  • New linter rules, line and column reporting, accurate summaries, and --init configuration scaffolding (#2831)
  • Support for V1, V2, and other V-prefixed integer resource versions across lookup, comparison, federation, and snapshots (#2815)
  • Ubiquitous language terms now support edit URLs and appear in indexed search (#2820, #2802)
  • Domain resource pages now include every directly attached resource, including subdomains, systems, agents, and data products (#2769)
  • AsyncAPI parser errors now render on the page instead of leaving a blank screen (#2777)
  • AsyncAPI generator now preserves shared references when saving parsed specification files (#445)
  • OpenAPI and AsyncAPI generators now escape angle brackets in descriptions so generated MDX continues to build (#447)
  • Historical message versions now show their version-specific producers and consumers (#2787, #2805)
  • Fixed container context-menu links opening entity URLs instead of container URLs (#2804, #2809)
  • Fixed a Windows development-server crash caused by backslashes in watched project paths (#2806)
  • Fixed LikeC4 diagrams in Vite development mode (#2823)
  • Fixed domain-owned entities appearing as external resources in entity maps (#2825)
  • Fixed embedded Architecture Graphs in static builds and missing domain System Diagram pages (#2839)
  • Updated vulnerable dependencies and bumped Astro and its integrations through 7.2.8 (#2771, #2818)

Thanks

Thanks to everyone who contributed to EventCatalog this month by opening issues, reporting bugs, and suggesting features, including Jonas Lagoni, Lucas Chabalier, Alex Dunne, Xavier Gouley, Ondrej Musil, and many more.

The detailed reports and fixes from the community helped us make the new v4 foundation more reliable while we kept building on it.

What's coming in September?

A few things we're working on:

  • Notifications for breaking changes
  • Better ways to capture breaking changes
  • Improvements to our Code-to-Docs workflows
  • Introducing community calls for EventCatalog

If you have any questions or want to join our community exploring EventCatalog and event-driven architecture feel free to join us!

Until next time!, Dave
Introducing EventCatalog Federation v2

· 7 min read

EventCatalog already works as a central catalog. Plenty of teams keep architecture, services, and messages in one place, and that is a good way to run it.

Federation is EventCatalog at scale. Once you have that central catalog, some organizations want to go further. They want distributed documentation: teams own their own docs, and the organization still gets one catalog it can trust.

Teams keep owning their services, their information, their architecture decision records, and everything else, next to their code. They federate that into a central catalog. People keep working autonomously. The organization still gets a catalog that updates itself from what teams already write.

Today, I am happy to announce EventCatalog Federation v2.

Federation is now built into EventCatalog. It is composition: distributed catalogs, composed into a central view. Catalogs stay with the teams that own the work. The organization catalog lists those sources, validates ownership and relationships, and materializes one connected view for humans and agents.

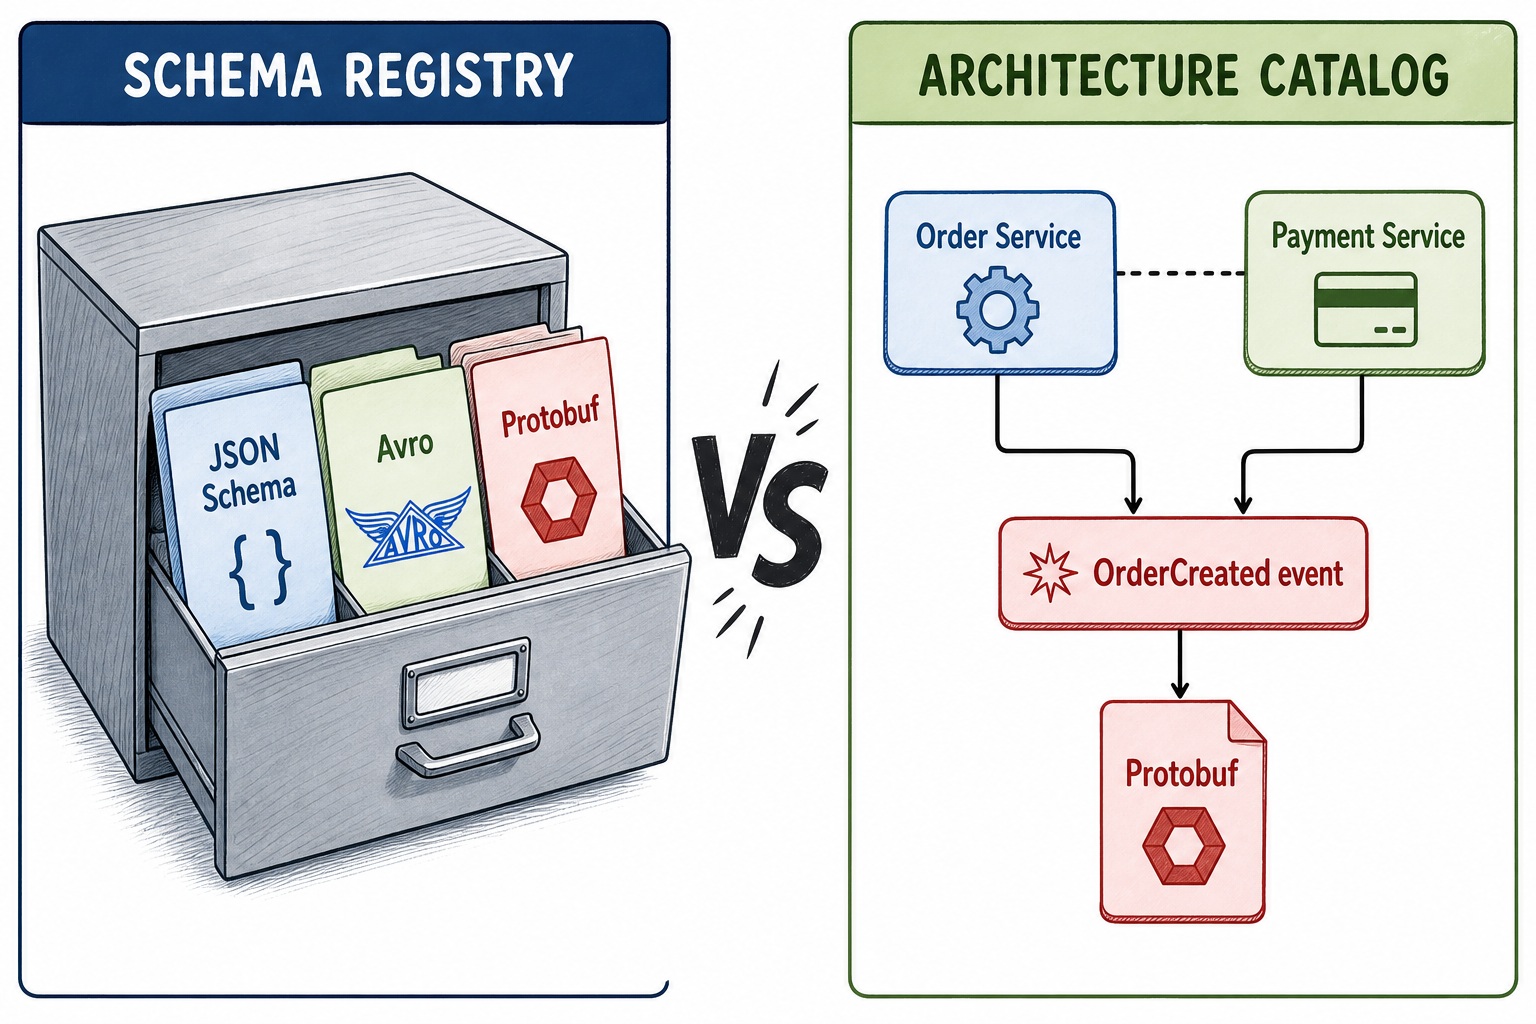
Schema registry vs Architecture Catalog

· 7 min read

A schema registry stores the contract: the shape of an event or message. An architecture catalog tells you how that contract fits the system: who produces it, who consumes it, which domain it belongs to, and what else breaks if you change it.

You often want both. A registry without a catalog is a drawer of schemas with no map. A catalog without schemas is a map with no contracts.

A schema registry shown as a filing cabinet of JSON Schema, Avro, and Protobuf files, versus an architecture catalog shown as a map of services around an OrderCreated eventA schema registry files the contract. An architecture catalog maps how that contract is used.

Whats new in EventCatalog - July 2026

· 13 min read
David Boyne
Founder of EventCatalog

Welcome to the monthly update for EventCatalog. July was our biggest release month so far. We shipped EventCatalog v4, and then kept shipping on top of it, moving from 4.0.0 all the way to 4.3.4 by the end of the month.

The theme was one we have been building towards for a while: EventCatalog is no longer only about documenting events. It is about documenting your software architecture, and giving both your engineers and your AI tools a graph they can actually reason about.

EventCatalog v4 and systems

EventCatalog started in 2022 as a small open source project for documenting events. More than 40,000 catalogs later, it is clear our community is not only documenting events, they are documenting their software architecture.

EventCatalog v4 is the first release shaped around that. The headline change is systems, a new first-class resource that sits between domains and implementation detail.

  • Domains describe a business boundary or bounded context.
  • Systems describe a software capability or an external system.
  • Resources describe the services, messages, flows, data stores, entities, and diagrams inside that system.

Your Payments domain might contain a Payment Processing System, and that system owns the API, the worker, the events, the data store, the checkout flow, and the entities involved in authorization and capture. It gives teams a natural place to document the thing they actually own, rather than a flat list of services.

Systems also define relationships to other systems and actors, and EventCatalog turns those into system context maps.

The context diagram answers "how does this system fit into the wider architecture?". Add <NodeGraph /> to a system page and you get the lower-level resource diagram too, which answers "what is this system made of?". Architects usually want the first view, engineers making a change usually want the second.

v4 also brought a single Catalog experience with a Kind filter (instead of separate explore pages per resource type), configurable navigation.groups for the application sidebar, and two capabilities moving into Community Edition: custom homepages and diagram comparison.

You can read more in the v4 announcement and the v4 upgrade guide.

Custom pages and API routes

Every organization eventually needs a page that does not fit a predefined resource type. A service scorecard. A migration tracker. A review workflow. A platform health dashboard that combines catalog structure with deployment and incident data.

As of 4.1.0, you can build those pages inside EventCatalog. Drop Astro files into a top-level pages directory and they get served alongside the rest of your catalog.

pages/reports.astro
---
import Layout from '@catalog/layouts/Layout.astro';
import { getServices } from '@catalog/utils';

const services = await getServices({ getAllVersions: false });
---

<Layout title="Service reports" description="Operational views built from catalog data.">
<p>There are {services.length} services in this catalog.</p>
</Layout>

That page is served at /custom/reports, and you can add it to the application sidebar with navigation.groups so it feels like part of the catalog rather than something bolted on.

API routes live in pages/api and give you the server-side half: expose catalog data as JSON, receive a form submission, proxy an internal platform, or pull service health from your observability tool. They need EventCatalog running in server mode.

If you use AI coding agents, there is a custom-pages-and-apis skill in our skills repository that gives your agent the conventions so you do not have to remember them yourself.

You can read more in the custom pages release post.

Map commands to the events they trigger

This one is my favourite from July, and it did not get its own announcement.

Your catalog has always been able to tell you that OrderService receives the CreateOrder command and produces OrderCreated and OrderRejected. What it could not tell you is which of those events came from which command, and under what circumstances. That relationship lived in someone's head, or in the code.

EventCatalog 4.2.0 adds a triggers property so you can map commands to the events they produce.

/services/OrderService/index.mdx
---
id: OrderService
version: 1.0.0
name: Order service
receives:
- id: CreateOrder
version: 1.0.0
triggers:
- id: OrderCreated
version: 1.0.0
condition: When payment is authorized and stock is available
- id: OrderRejected
version: 1.0.0
condition: When payment fails or stock is unavailable
---

The optional condition is what makes this genuinely useful. It lets you document the scenario, so a command producing a success event or a failure event, a branch driven by a business rule, or two different paths that happen to produce the same event, are all visible on the page rather than implied.

The relationship is bidirectional. Commands list their events under Triggers, and each event page lists the commands that can produce it under Triggered by. Messages that take part in at least one resolved relationship also get a dedicated Map commands to events page, with one visual row per path and its scenarios.

The same release improved the visualiser: the resource you are currently viewing now stays visibly marked as the focus of the graph, context menus let you focus another node in its own map, and edge labels render above edges so intersecting paths no longer hide their text. Trigger pointers are supported in the SDK too.

Scoped MCP servers

More context is not always better context.

Our MCP server already let AI tools query your entire architecture, which is exactly what you want for organization-wide dependency questions. But most engineers spend their day inside a much smaller boundary, and an agent loading Shipping, Identity, and Analytics resources to answer a refunds question just adds noise.

From 4.3.0, EventCatalog exposes a scoped MCP endpoint for every domain and system.

https://your-eventcatalog.com/docs/mcp/domains/payments
https://your-eventcatalog.com/docs/mcp/systems/payment-processing/1.2.0

Your AI tool can now connect at the level that matches the question it needs to answer:

Open a domain or system page, select Connect to MCP server, and you get a URL for that part of the catalog. The scoped server includes the selected resource and follows its relationships recursively, so the client gets the connected architecture graph including services, messages, schemas, flows, ubiquitous language, and ADRs, without pulling in unrelated parts of the catalog.

Connect a team's tooling to the domain they own once, and engineers stop having to restate boundaries in every prompt. The same release added an mcp.enabled config option if you want to turn the built-in server off entirely.

You can read more in the scoped MCP servers release post.

Custom properties on resources

EventCatalog gives you first-class fields for the common concepts: owners, messages, relationships, schemas, repositories. But every organization has metadata that is specific to its own platform and processes, and until now there was nowhere clean to put it.

4.2.3 adds custom properties. Any top-level frontmatter field prefixed with x- is treated as your own metadata.

/services/PaymentAPI/index.mdx
---
id: PaymentAPI
name: Payment API
version: 1.0.0
x-operational-tier: 1
x-on-call:
schedule: payments-primary
escalation-channel: '#payments-incidents'
---

Values can be strings, numbers, booleans, arrays, or nested objects, and they work on domains, systems, services, agents, messages, channels, flows, containers, entities, data products, diagrams, and ADRs. New <CustomProperties> and <CustomProperty> MDX components render them on the page, so operational tiers, recovery objectives, and on-call schedules can live next to the architecture they describe.

A better Discover experience

Two small changes that make a big difference when your catalog gets large.

Discover table filters now persist in the URL. Searches, filters, and toggles survive a page reload, and more importantly you can share a filtered view as a link rather than telling someone which six filters to click.

Domains also got a type filter for root domains and subdomains, and subdomains now render nested under their parent in the name column. If you use subdomains heavily, the list finally reflects the hierarchy you actually modelled.

Schema Explorer improvements

The Schema Explorer's version comparison used to only show you consecutive-version diffs, which is fine until someone asks "what changed between 1.0.0 and 2.3.0?".

You can now pick any two versions to diff using From/To selectors. We also fixed $ref resolution for remote JSON schemas, so local and remote pointers are inlined properly instead of rendering as unresolved $ref values, and fixed SchemaViewer portal targeting when multiple schemas share the same id on a page.

Entities go deeper

Entities picked up recursive embedded properties in 4.3.2, so you can model nested structures properly rather than flattening them out. You can also opt in to whole-entity relationship targets, embedded properties render in both entity documentation and visualiser nodes, and generated entity maps come out more compact.

Other project improvements

  • Custom documentation tools (getCustomDocs, searchCustomDocs, getCustomDoc) added to AI Chat and the MCP Server, with section-level full-text search (#2670)
  • New getGraph API in the SDK (#2726)
  • SDK support for architecture decision records (#2659)
  • Linter support for the new system resources (#2665)
  • create-eventcatalog can now optionally install EventCatalog Skills when scaffolding a new project (#2688)
  • Stable, versionless URLs for the latest service's specifications, changelog, and attached documentation (#2740)
  • Navigation loading indicator so slower SSR page transitions give feedback instead of appearing unresponsive (#2722)
  • Improved sidebar group collapsing, persistence, and resizing (#2743)
  • Bumped to Astro 7.1.1 with updated @astrojs integrations (#2723)
  • Fixed: static builds crashing with TypeError: Missing parameter: id when trailingSlash: true (#2690)
  • Fixed: AI chat API URL not respecting a custom base path (#2682)
  • Fixed: cropped and colorless visualiser image exports (#2683)
  • Fixed: changelog diffs and raw Markdown endpoints resolving the wrong file paths in SSR deployments (#2712, #2708)
  • Fixed: the linter failing to load dependencies from an ESM eventcatalog.config.js (#2678)
  • Fixed: sidebar collapse state for ADR status groups (#2731)
  • Fixed: proper favicons served instead of the logo image (#2697)
  • Removed the EventCatalog DSL import command and Compass playground integration from the CLI (#2738)

Thanks

Thanks to everyone who contributed to EventCatalog this month by opening issues, reporting bugs, and suggesting features, including Benjamin Otto, Alex Dunne, omid eidivandi, Dominik Szczepaniak, Wenzel, Max Dobler, Jan, Christian Johansen, and many more.

Shipping a major version and then iterating on it this fast only works because people tell us what broke.

What's coming in August?

A few things we're working on:

  • More improvements to systems, context maps, and the Catalog experience now that v4 is out
  • Continued work on EventCatalog Agent and the Code-to-Docs workflow
  • More ways to bring catalog context into the tools your teams already use

If you have any questions or want to join our community exploring EventCatalog and event-driven architecture feel free to join us!

Until next time!, Dave

Scope your MCP server to a domain or system

· 7 min read

More context is not always better context.

EventCatalog's MCP server already lets AI tools and agents query your entire architecture. That is useful when you need to understand organization-wide dependencies, but most engineers spend their day working inside a much smaller boundary.

You can now connect an MCP client to a specific domain or system. Your team gets the architecture knowledge it needs, including the connected services, messages, schemas, flows, language, and decisions, without pulling unrelated parts of the catalog into every conversation.

Add custom dashboards, tools, and APIs to EventCatalog

· 6 min read

Every architecture catalog starts with the same goal: help people understand the systems they work with.

But every organization eventually needs pages that are specific to how it works. A platform team might need service scorecards. An architecture team might need review workflows. An engineering team might want a page that combines ownership, deployment state, incidents, and catalog data in one place.

Custom pages and API routes let you build those experiences inside EventCatalog.

Introducing EventCatalog v4

· 10 min read

EventCatalog started in 2022 as a small open source project for documenting events in event-driven architectures.

Since then, more than 40,000 catalogs have been created by teams around the world. Along the way, EventCatalog has grown beyond events. Teams are using it to document domains, services, schemas, specifications, ownership, diagrams, and the relationships between them.

That has made one thing clear: our community is not only documenting events. They are using EventCatalog to document their software architecture.

Our new vision

Most documentation tools are not designed for software architecture. They are built around generic pages, folder trees, and diagrams that often live outside the context of the systems they describe.

Over time, that information gets scattered. Pages drift from production reality, diagrams become stale, and teams stop trusting the documentation.

We believe there must be a better way.

Architecture documentation should reflect the way architects and engineers already think and model systems. It should use primitives and patterns they understand: domains, systems, services, messages, schemas, ownership, flows, and diagrams.

It should also stay connected to the real architecture. Specifications, registries, code, and documentation should be able to move together, because documentation is a living artifact, not something you write once and forget.

This information should also be accessible to AI agents and AI-assisted engineering tools. EventCatalog is not just a set of pages, it is a graph of your architecture: the domains, systems, services, messages, schemas, owners, and relationships that explain how your organization works. That graph gives AI tools the context they need to reason about real software systems, not a generic version of them.

This is the direction we are taking EventCatalog. We believe EventCatalog can become the open source documentation tool architects use to describe, understand, and evolve their software architecture. That means going beyond events and giving teams better ways to document the systems, boundaries, resources, and relationships that make up their organization.

Today, I am happy to announce EventCatalog v4, the first release shaped around this vision.

This release introduces:

  • Systems: a new way to document software capabilities, external systems, and the resources that belong to them.
  • Clearer architecture levels: domains, systems, and resources now give teams a more natural hierarchy for moving from the big picture to implementation detail.
  • A simpler, more generous Community Edition: more capability is available without needing a commercial license.
  • Simpler licensing: clearer plans for teams that want to take their catalog further with Scale.

Bring live data into EventCatalog

· 8 min read

Your architecture documentation should explain how your systems work. Sometimes it should also show what is happening around those systems right now in real-time.

With custom components, EventCatalog can fetch data from your internal platforms, monitoring tools, schema registries, deployment systems, and service catalogs. That means a service page can show the architecture model, the schema, the owner, the latest deployment, and the current health signal in one place.

Custom components turn EventCatalog pages into living documentation surfaces.

How to turn C4 diagrams into EventCatalog documentation

· 9 min read

Lots of teams already use C4 to model their architecture, whether that's Structurizr DSL, C4-PlantUML, Mermaid C4, LikeC4, or just markdown architecture docs. If that's you, the good news is you can bring that work straight into EventCatalog.

C4 and EventCatalog complement each other nicely. C4 gives you a clear view of your structure: systems, containers, and how they fit together. EventCatalog adds the event-driven detail on top: the events flowing between services, the schemas, who owns what, and how a business process actually runs. Today I want to show you two ways to connect the two.

Whats new in EventCatalog - May 2026

· 11 min read
David Boyne
Founder of EventCatalog

Welcome to the monthly update for EventCatalog. May was one of our biggest months yet, and there was a clear theme running through it: your catalog should be the source of truth for the humans building your system and the AI agents working alongside them.

We made agents and architecture decisions (ADRs) first-class resources, shipped a visual editor in beta, and added full-content search, GitHub user sync, and a set of features aimed squarely at coding agents. Here's everything that landed.

Document and Govern AI Agents

Most companies are not going to have one agent. They are going to have many. One team adds a support agent, another adds a fraud review agent, another adds an internal architecture assistant. Each one consumes events, calls tools, reads data, and produces work that downstream systems depend on. If an agent influences your system, it needs to be visible in the same place as the rest of your architecture.

EventCatalog 3.41.0 adds agents as a first-class resource. Each agent gets its own page, frontmatter API, sidebar entry, search result, visualizer node, ownership metadata, and version history.

For each agent you can document who owns it, which model it uses, which tools (MCP servers, APIs, databases, search indexes) it can call, which messages it consumes and produces, and which data stores it reads from or writes to. Agents also show up in the visualizer and can be used as nodes in flows, so you can see exactly how information moves between agents, services, messages, and data.

A huge thank you to Martijn van der pauw for raising the original RFC and helping shape this one.

You can read more about agents in our release blog post here.

Architecture Decision Records

Your catalog tells you what services exist, what events they produce, what schemas look like. What it hasn't told you is why any of it was built the way it was. Why Kafka over RabbitMQ. Why the Orders domain owns customer address data. Decisions separated from the things they describe are decisions that get made again, usually with incomplete information.

Architecture Decision Records are now a first-class resource in EventCatalog. They have frontmatter, versioning, and markdown content, and they show up in search, the Discover page, and the visualizer alongside everything else.

An ADR document rendered in EventCatalog showing status, context, decision, and consequences

The most useful part is the appliesTo field, which links an ADR directly to the services, events, commands, and domains it governs. Those links are bidirectional, so when someone views OrdersService they see the decisions that shaped it, right at the point where it matters. ADRs also track lineage through supersedes, amends, and related, and because they live in the catalog the MCP server can answer "why did we choose Kafka for the Orders domain?" by reading the actual decision record.

You can read more about ADRs in our release blog post here.

EventCatalog Editor (Beta)

Catalog maintenance is not only an engineering task. Architects, analysts, and product owners often know what needs to change, but the source files, frontmatter, schemas, and Git workflow slow them down.

EventCatalog Editor is now in beta. It gives your team a local visual editor for maintaining the same EventCatalog files you already keep in Git. You can edit resources, preview changes, review diffs, and publish local commits without opening Markdown for every update.

The editor runs locally on top of your catalog and writes changes back to the same files, so your existing review and release process stays in place. Highlights include a visual Flow Editor for building flows by shape rather than YAML, a changes view that groups local Git diffs by resource before you publish, and slash commands for inserting diagrams, callouts, prompts, and resource-aware blocks without remembering the syntax. Source mode is always one click away when you need it.

You can read more about the Editor in our release blog post here.

The default search is fast and works everywhere, but it only sees frontmatter-level data: names, identifiers, types, summaries, and badges. If the detail you need is buried in a message payload description, a changelog entry, or a custom architecture doc, the default search will not find it.

EventCatalog v3.36.0 adds indexed full-content search. It reads the body of every page in your catalog, powered by Pagefind. If a term appears anywhere in your documentation, it shows up.

Enabling it is one line in your eventcatalog.config.js:

// eventcatalog.config.js
export default {
// ... rest of your config
search: {
type: 'indexed',
},
};

The index builds automatically during eventcatalog build and eventcatalog dev, with debounced rebuilds whenever a .md or .mdx file changes. Results are ranked so titles and identifiers score highest, then summaries, then body content. One note for auth-protected catalogs: Pagefind stores full page content in a /pagefind directory, so protect it with the same auth layer as your pages.

You can read more about indexed search in our release blog post here.

Sync users and teams from GitHub

Teams and users are how you assign ownership in EventCatalog, and ownership is only useful when it is accurate. Keeping a list current by hand is not sustainable. People join and leave teams, teams get restructured, and the catalog falls behind until nobody trusts the data.

EventCatalog can now sync users and teams directly from GitHub. Point the new githubDirectory connector at your org, list the teams you care about, and ownership data stays accurate automatically.

If your team data lives somewhere else, an HR tool, LDAP, Okta, or Microsoft Entra, you can build your own connector with defineDirectorySource. The same sync mechanism runs regardless of the source. Directory sync is a Scale plan feature (and available on Enterprise), but the connector package is open source so you can build and test locally.

You can read more about GitHub sync in our release blog post here.

Docs your AI agents can trust

I've been using Claude Code and Cursor every day on EventCatalog, and I kept hitting the same thing: the agent would confidently spit out frontmatter that didn't exist or point at folders we'd renamed months ago. It's not really the agent's fault, it's working from a snapshot of the web that's months out of date, and EventCatalog moves fast.

As of 3.35.1, the full EventCatalog docs are bundled inside the npm package, version-matched to whatever you have installed. After a normal install they live at node_modules/@eventcatalog/core/dist/docs/. No extra install, no network request, no version mismatch. New projects scaffolded with create-eventcatalog get an AGENTS.md and CLAUDE.md that tell any coding agent to read those docs before generating anything.

You can read more about bundled docs in our release blog post here.

Prompt and Visibility components

Writing docs that serve both a human reading the UI and an AI agent consuming raw markdown used to mean maintaining two versions of the same information. That overhead compounds fast across a large catalog.

EventCatalog 3.33.0 ships two new MDX components to fix this:

  • <Prompt /> embeds a copyable AI prompt block directly on any resource page, with one-click copy to clipboard or open in Cursor.
  • <Visibility> gates content by audience in a single file. Humans see one block in the UI, AI agents see another in the raw markdown. The same file, zero duplication, two audiences.

You can read more about both components in our release blog post here.

API catalog discovery

Developers and agents should not need to crawl your docs site to find the contracts your team already publishes. They should be able to ask one known URL and get a machine-readable answer.

EventCatalog can now publish an API catalog at /.well-known/api-catalog, following RFC 9727. The endpoint returns a Linkset of every service and domain with OpenAPI, AsyncAPI, or GraphQL specifications attached, plus the EventCatalog MCP endpoint when enabled. Your catalog already knows where your APIs live, this exposes that knowledge in a format developer tools and agents can consume directly.

You can read more about API catalog discovery in our release blog post here.

Flows reach the data layer

Flows let you document end-to-end business workflows across services, messages, actors, and external systems. Until now they stopped at the application layer and went silent the moment data landed somewhere or fed into a report.

v3.36.3 adds two new flow node types, container and dataProduct, so your flows can reach into the data layer. A container step references a data store, and a dataProduct step references a data product. You can now draw the complete picture in a single diagram: the services that process events, the data stores they write to, and the data products built on top.

Bidirectional linking is automatic. When a flow references a container or data product, that resource's sidebar gains a "Flows" section listing every flow that touches it.

You can read more about the new flow nodes in our release blog post here.

Other project improvements

  • Added search configuration so you can customize what the search modal indexes (search docs)
  • <AgentTools /> component renders the tools an agent can call directly on its page
  • Slash commands in the Editor for inserting diagrams, callouts, steps, tiles, and prompts
  • ADR status field tracks the full lifecycle: proposed, accepted, deprecated, superseded
  • Auth support added to the EventCatalog Editor for Cloud seats
  • New @eventcatalog/connectors package for syncing directory data from external systems

What's coming in June?

A few things we're working on:

  • Continued polish on the EventCatalog Editor as we move it through beta toward general availability
  • More ways to document and govern AI agents as the resource type matures
  • Deeper AI-native workflows building on bundled docs, the MCP server, and skills

If you have any questions or want to join our community of over 1,200 people exploring EventCatalog and event-driven architecture feel free to join us!

Until next time!, Dave

Your architecture decisions belong next to your architecture

· 7 min read

Your catalog tells you what services exist, what events they produce, what schemas look like. What it hasn't told you is why any of it was built the way it was.

That's the job of Architecture Decision Records. ADRs capture the reasoning behind significant design choices: why you chose Kafka over RabbitMQ, why the Orders domain owns customer address data, why you split the Payments service the way you did. EventCatalog now supports ADRs as a first-class resource, so that reasoning lives exactly where people go when they need to understand your architecture.
